

I just published a piece in Katina Magazine (formerly Charleston Advisor) covering Scholar Labs, Web of Science Smart Search and Consensus.
This joins two pieces I contributed last year to the same publication: My Deep Dive into Web of Science Research Assistant, Primo Research Assistant and Scopus AI and A Librarian’s Guide to AI in Academic Search Tools.
Nothing in it is really new if you have been following my posts closely, but it does provide a more holistic overview of how academic search tools and providers are adapting to changes in AI, covering concepts such as agentic search, Deep Search and MCPs.
I don’t publish in the formal literature frequently, at most once or twice a year, mostly because there are few incentives for me to do so. So why Katina?
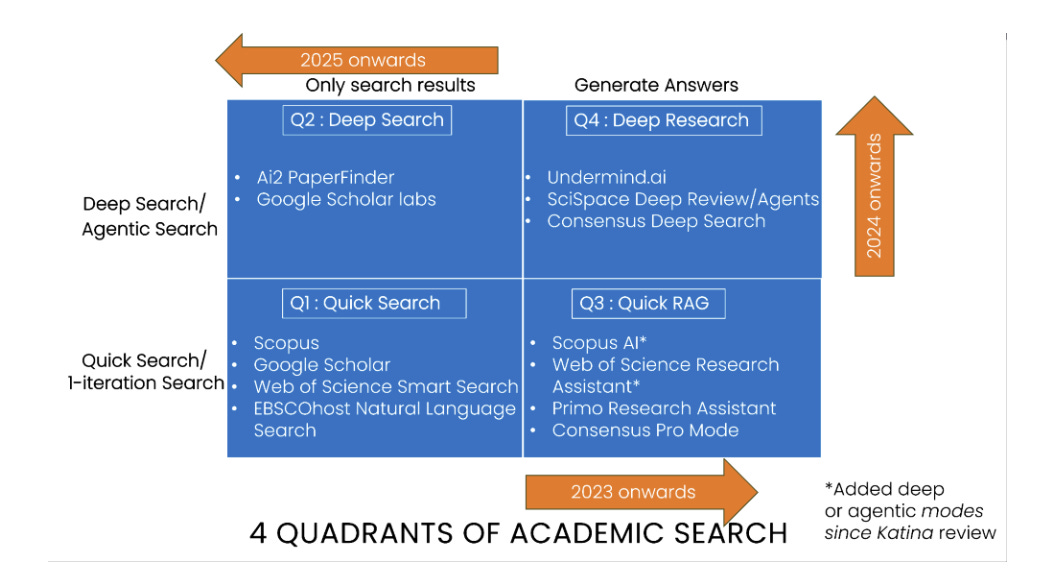
I must admit that part of what motivated me to write this piece was to give researchers and librarians who wanted to cite the idea a more formal source for the 2×2 matrix, the “4 Quadrants of Academic Search”, which I first introduced in a blog post in August 2025. Since then, I’ve received a few questions about how and where to cite it.
I also had a pretty good experience publishing in Katina last year, and my pieces seem to have been widely read and appreciated. One even made it onto the journal’s list of the ten most-read pieces of the year.
At the end of the day, that’s what I hope to see. I truly enjoy researching and studying things deeply and sharing what I figured out.
The fact that my writing seems to be helping librarians and researchers get a better grasp of what is happening around “AI search” is truly satisfying to me.
Two new Scopus “AI search” features in Aug 2026
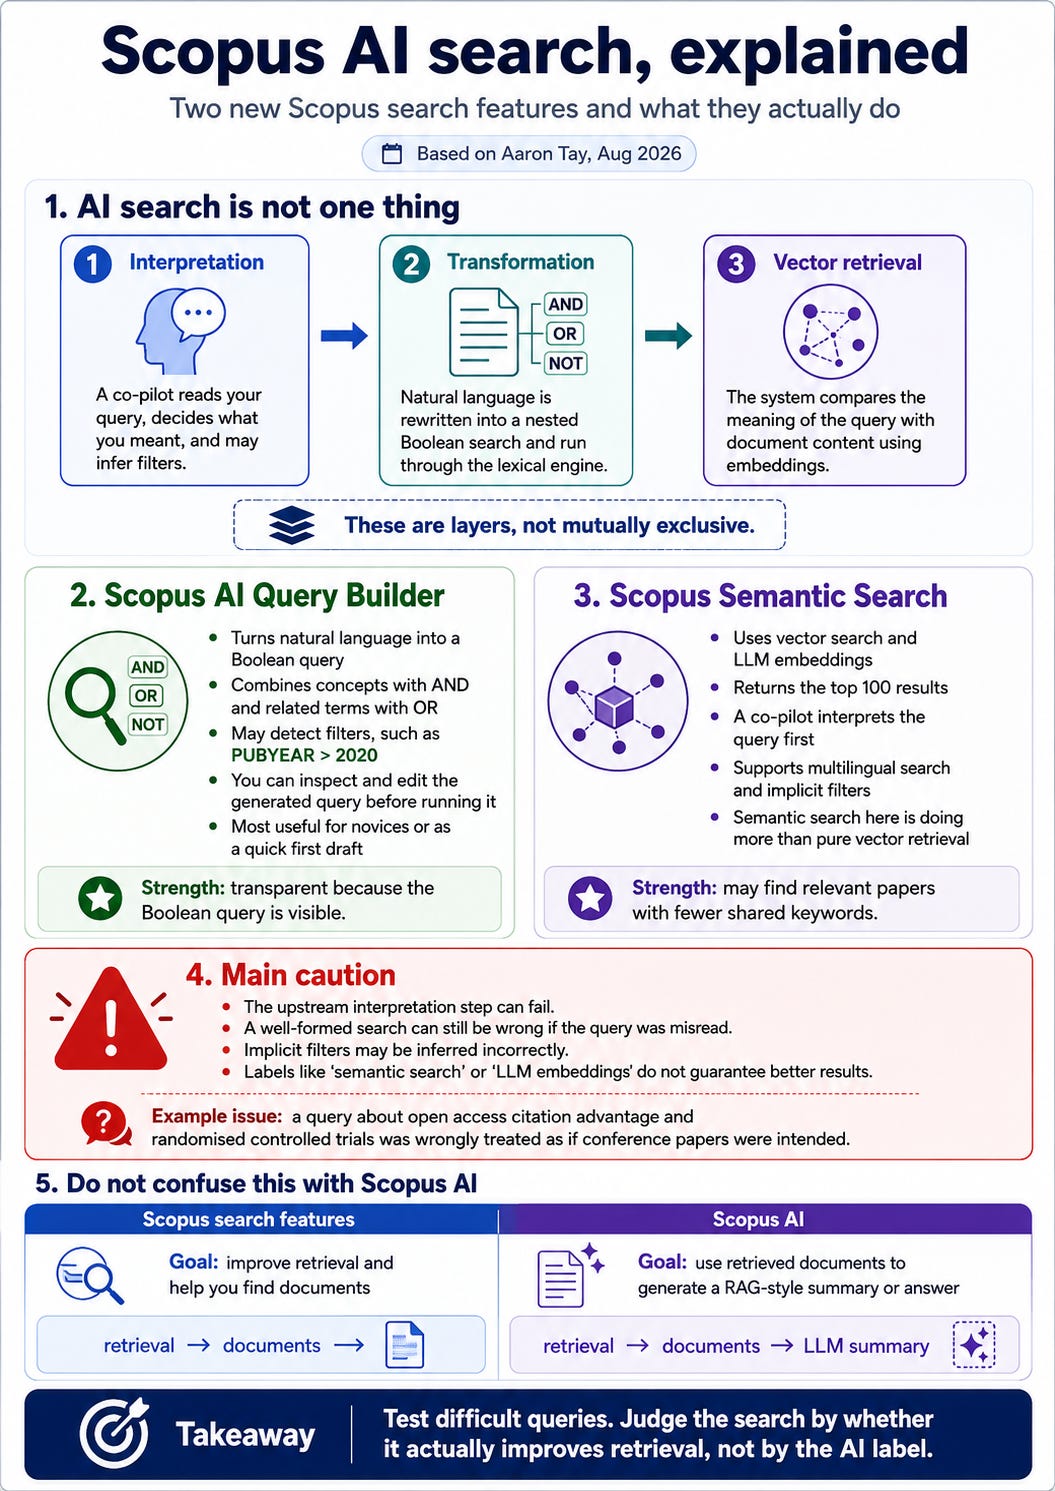
One of the misconceptions I try to fight when writing about this area is the idea that “AI search” is one particular thing.
In a conventional academic database, “AI search” now describes at least three things1 , and they can sit on top of each other
Interpretation. An LLM reads your query, decides what you meant, and decides which filters you implied.
Transformation. Your query is rewritten into a nested Boolean strategy and run through the existing lexical engine.
(Vector) Embedding2 retrieval. Your query is converted to vector embeddings and is matched against document vectors to find the closest documents - commonly called “semantic search”
You can see these as features, but they may be better understood as layers, because they are not mutally exclusive, and each fails on its own terms even when used in combination. For example, a well-formed Boolean strategy built from a misread query returns precise, clean, irrelevant results due to the wrong filter applied.
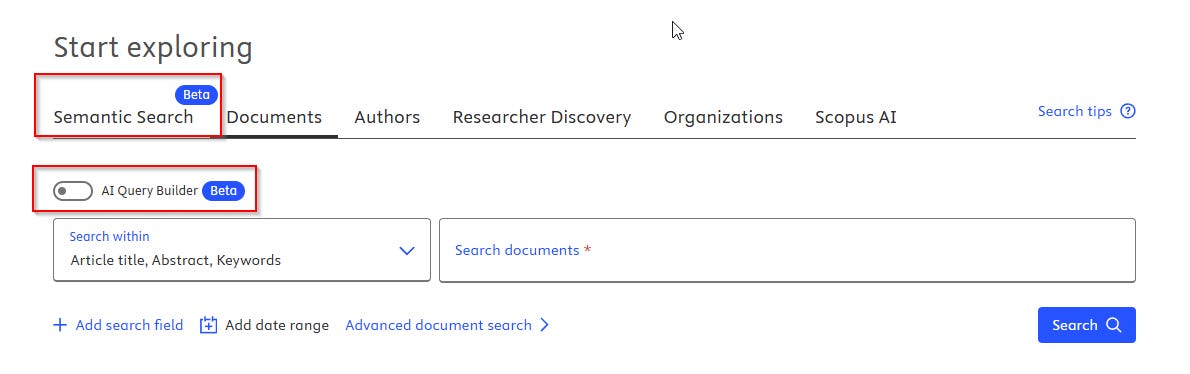
And almost on cue, Scopus has just rolled out two new search features that illustrate this nicely in August 2026.
Scopus AI Query Builder
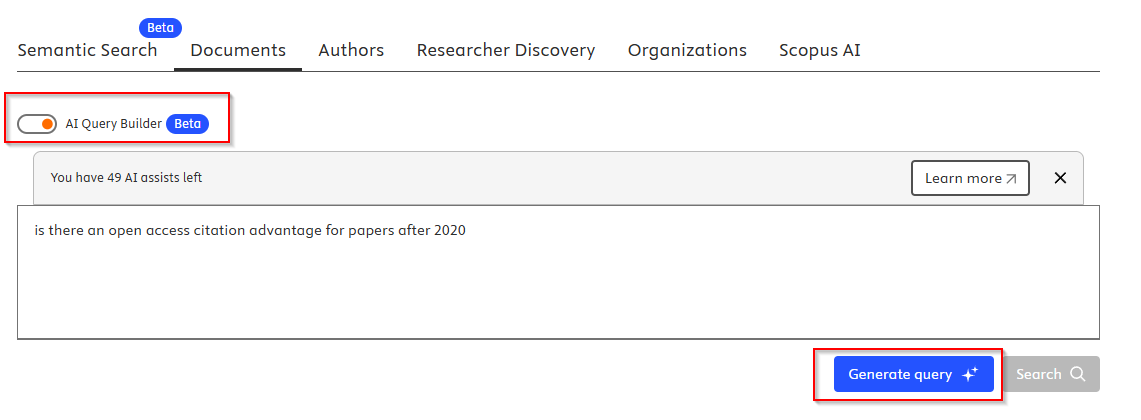
Scopus AI Query Builder converts your query, typically expressed in natural language, into a Boolean query.
AI Query Builder Co-pilot sanitises the natural language input, then breaks down a question into concepts and keywords. Concepts are combined with AND, while related keywords are combined with OR to construct a Boolean query. The generated query can be edited manually before running the document search.
Similar to other academic AI search features such as Primo Natural Language Search and EBSCO’s AI-Assisted Search (formerly Natural Language Search)3, this feature can not only break your query into concepts, add synonyms and create a nested Boolean search strategy, but also apply filters when it detects a user intent to do so.
In the example below, you can see that it correctly interprets the query and adds a filter for PUBYEAR > 2020.
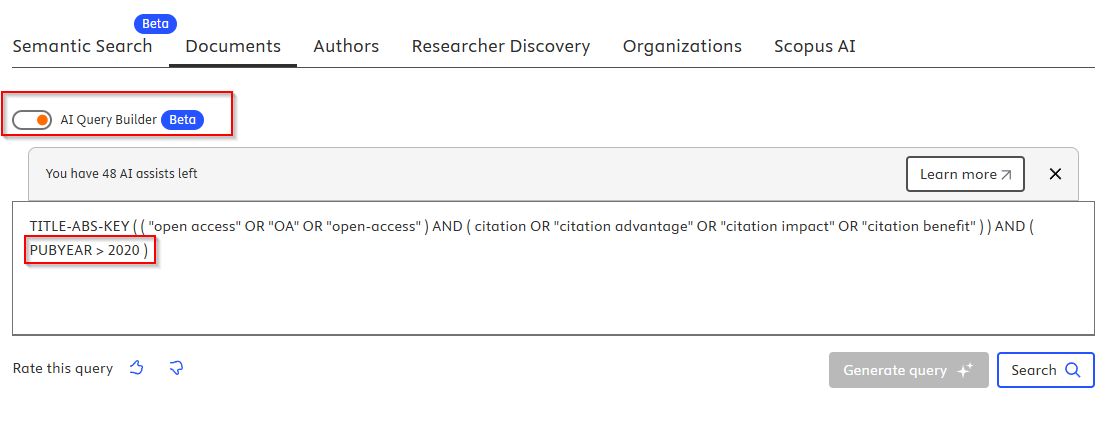
The documentation isn’t clear on whether the conversion to Boolean uses an LLM, though it probably does.
One interesting difference is that, unlike Primo Natural Language Search and EBSCO’s AI-Assisted Search, Scopus AI Query Builder doesn’t automatically run the generated Boolean search. You can inspect and edit it before running the search.
I have argued in the past that such features probably won’t help advanced searchers much and are more likely to benefit novices. But they do have some utility. Even advanced users might find them convenient for producing a quick first draft of the Boolean before editing it.
That said, vendors offering such features should clearly document which fields their query interpreter supports.
For example, if you ask in natural language to restrict results to particular author affiliations or journal titles, will it interpret those correctly with the right filter turned on? So far, based on my tests, the answer seems to be no for the former and yes for the latter.
Documenting this would make the feature much more transparent to users.
Scopus Semantic Search
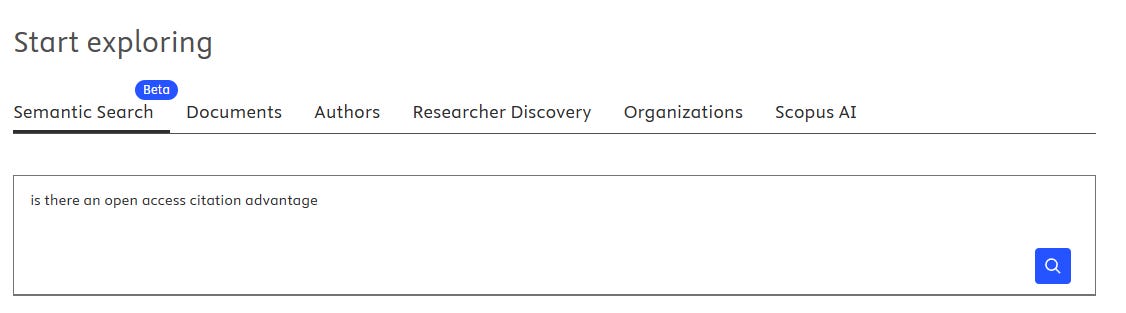
The other new AI feature added is Semantic Search, which Elsevier describes as follows:
Semantic Search compares the meaning of the user’s query with document content using vector search and LLM embeddings4. It retrieves the most relevant results and supports additional tools to help users refine, review, and understand the result set.
This is probably what many people now have in mind when they hear ‘semantic search’ - embedding-based vector retrieval.
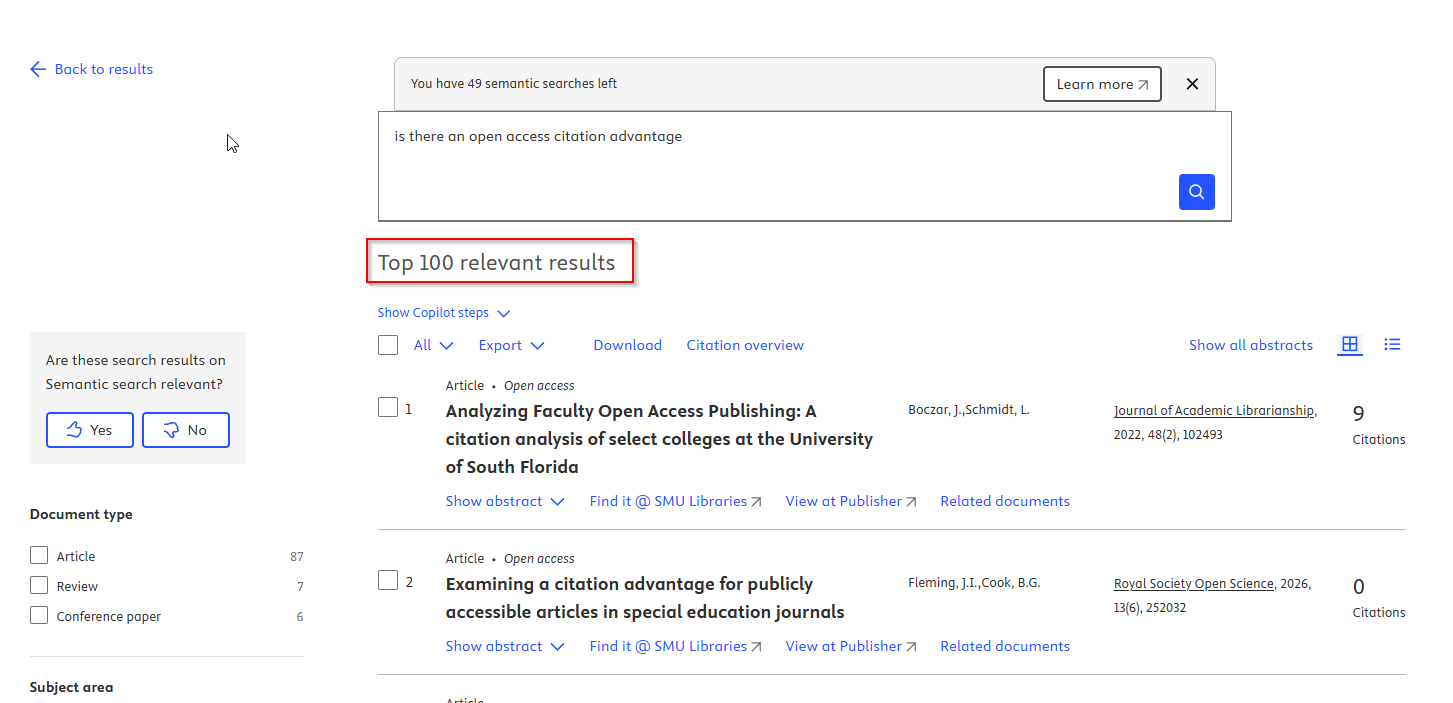
This Semantic Search returns the top 100 results, which is what you would expect from a top-k vector retrieval system operating over a large index5.
Incidentally, the semantic-search component of Web of Science Smart Search also returns the top 100 results.
Except Semantic Search is doing more than vector search
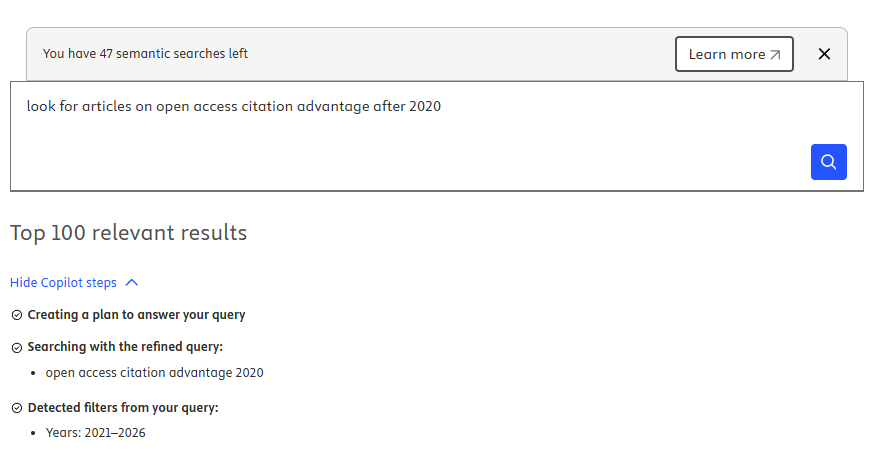
When you use Semantic Search, Scopus doesn’t simply pass your original query directly to the vector retrieval system. A “Co-pilot” first processes it.
Semantic Search Co-pilot sanitises the query, interprets the query intent, allows multi-language search, supports implicit filters (Date, Country, Document Type)
As you can see above, the Co-pilot can detect “implicit filters” that should be applied. But although it correctly detected a publication-year restriction, the resulting 100 documents did not appear to apply it.
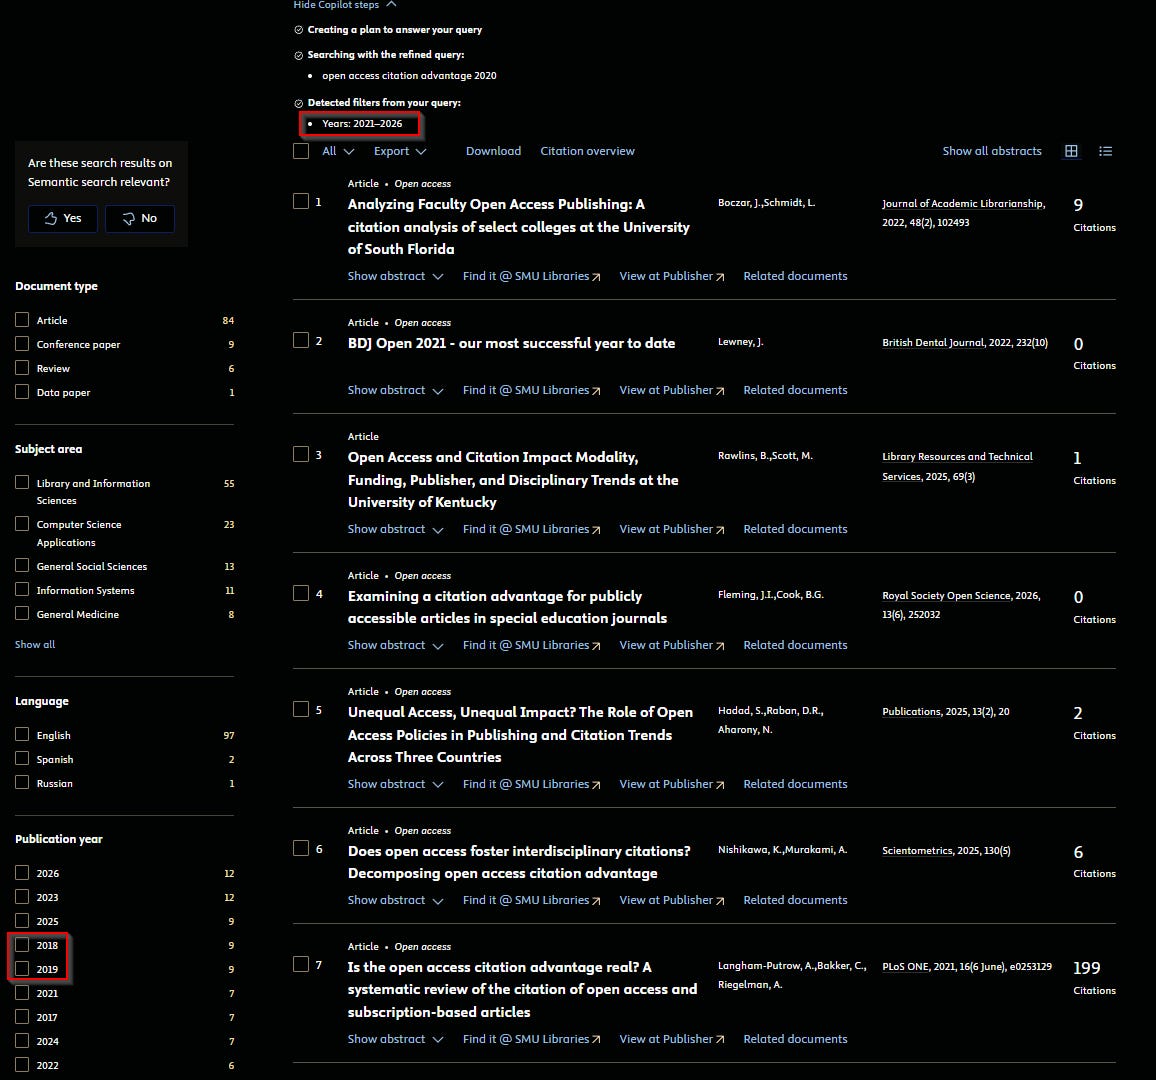
If “supports implicit filters” means those detected filters are supposed to constrain retrieval, this looks like either a bug or an incomplete implementation.6 ?
I have found that the Co-pilot can be rather hit-or-miss. For example, it decided a query “is there an open access citation advantage. i want papers that only use randomized control trials”, implied I was looking to filter to conference papers!
Fortunately, as noted above, filters detected by the Co-pilot do not appear to be applied automatically to the search.
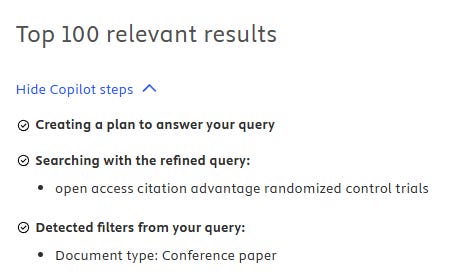
Still, it illustrates something I think is becoming increasingly important.
With a traditional database query, you worry about whether your query accurately expresses what you intended.
With an AI-mediated search, you increasingly also have to worry about whether the system’s interpretation of your query accurately expresses what you intended.
Comparison with other related products
I can’t help but compare these two new Scopus AI features with their obvious rival: Web of Science Smart Search.
In both cases, these features are effectively “bundled in” for subscribers to the base Scopus or Web of Science product.
Interestingly, Scopus currently allows only five searches per day for each of AI Query Builder and Semantic Search, rising to 50 if your institution subscribes to Scopus AI. That seems overly cautious to me.
We may be seeing an emerging consensus: “AI” features that improve retrieval, rather than generate synthesised answers across multiple records (e.g. Scopus AI, Web of Science Research Assistant, Leapspace), will increasingly be bundled into the core product7.
Interface decisions
In the past, you entered a search query and it would typically be run through a lexical search engine, perhaps with some stemming or other light processing. The matches would then be ranked using something like BM25 or TF-IDF ranking based on lexical signals, potentially combined with other signals such as citation counts.
Today, the same search box might do any combination of the following:
1. Run the query through an interpreter to detect things such as dates, document types or other intended filters.
2. Convert the query into a nested Boolean search strategy and run it through the existing lexical search engine.
3. Use the query for vector-embedding retrieval.
4. Combine two or more of the above.
How best should the interface convey such choices to the user? What should be the default?
Scopus’s current solution is to expose #2 and #3 separately, through AI Query Builder and Semantic Search respectively, although some form of #1 also appears in both.
Web of Science Smart Search takes a different approach. By default, it combines the Boolean and semantic retrieval paths, roughly #2 and #3 above, and then allows users to restrict the results to Boolean or semantic matches separately.
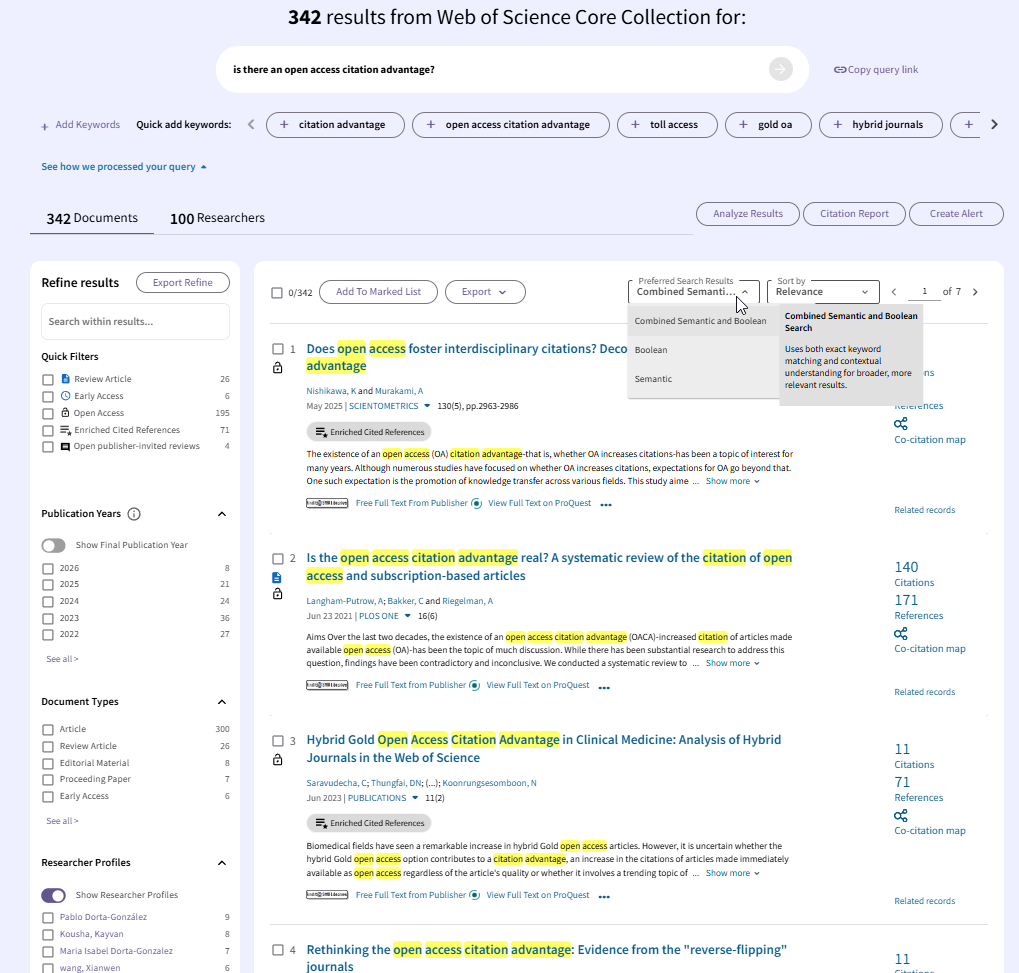
I currently prefer this approach. If configured well, it gives users the best of both worlds without forcing them to decide upfront which retrieval method to use. Showing users multiple separate options strikes me as sub-optimal because most users will not know which one to choose.
However, it can be more expensive of course.
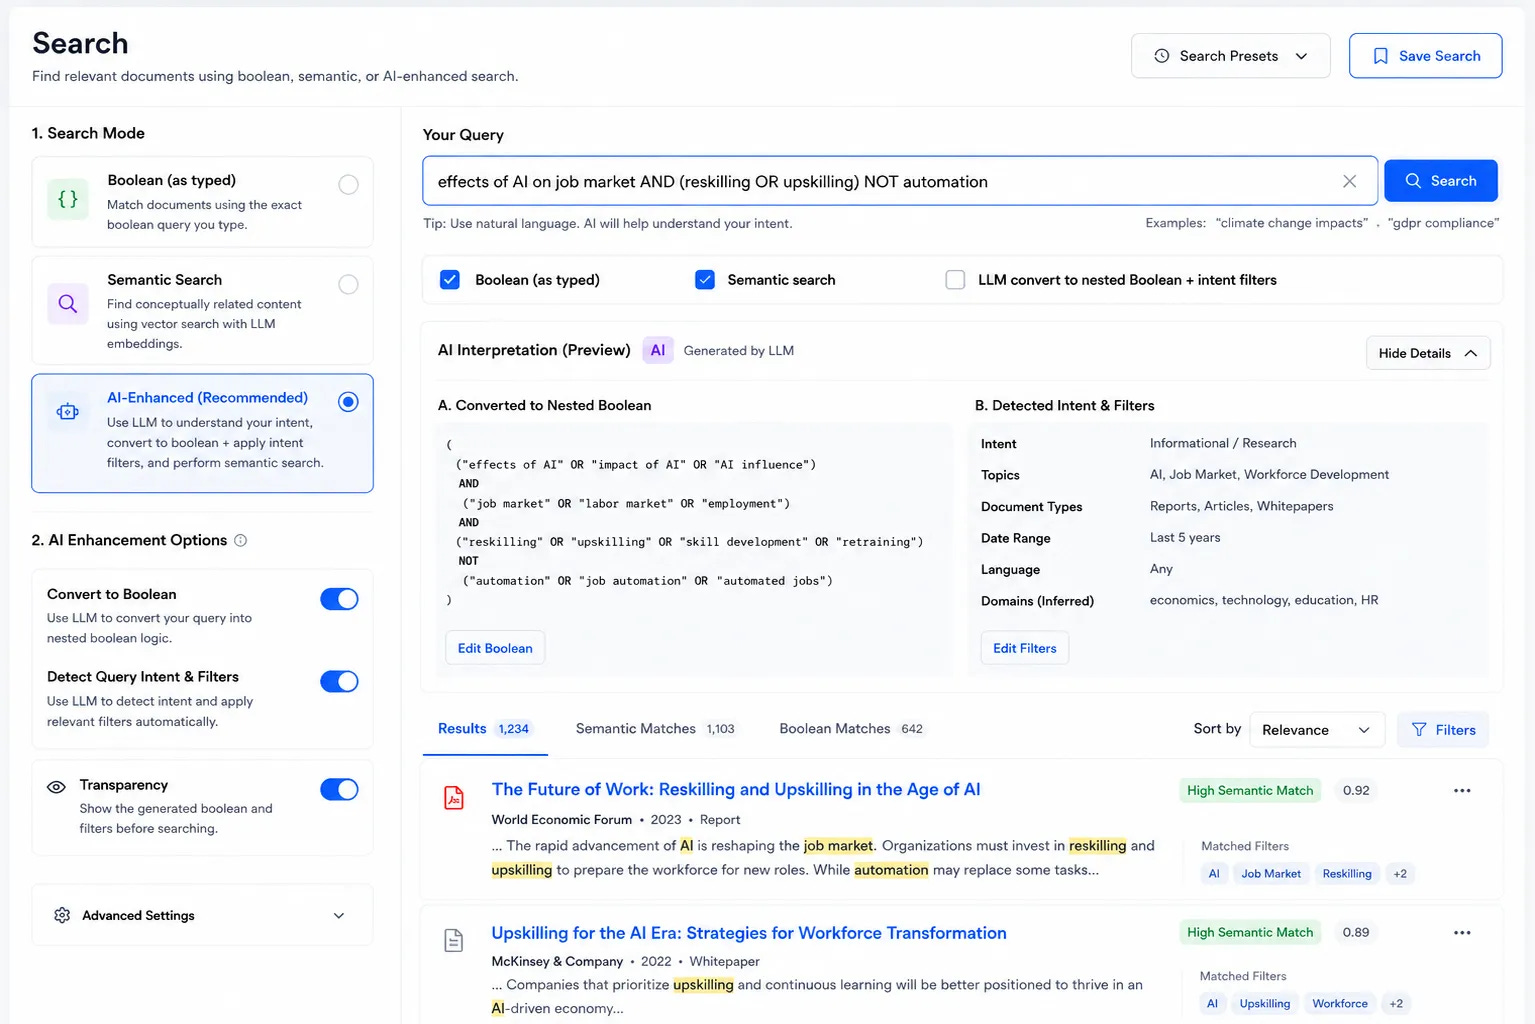
One can imagine other interface possibilities, such as checkboxes that let users independently turn semantic search or LLM-to-Boolean conversion on and off. Here is one (ugly) example.
Conclusion
Academic search now has multiple retrieval tools and vendors are experimenting with options on how to expose them to users.
One word of caution: these are all potential benefits. LLM-generated Boolean searches may help users formulate better queries. Semantic search may retrieve relevant documents that share few keywords with the query. But neither capability definitely or automatically improves search.
These features can be, and often are, implemented poorly enough that they bring little or no benefit over conventional search.
My current impression is that some implementations I have tested so far appear to add surprisingly little over conventional search.
Librarians should therefore be wary of taking labels such as “semantic search” or “LLM embeddings” at face value, or of being dazzled by systems that automatically expand concepts and infer filters. None of this guarantees that the search will actually be better.
Moreover, with an AI-mediated Co-pilot search, you also have to worry about whether the system’s reading of your query expresses what you intended and does not turn on the wrong filter. That is a second point of failure, it sits upstream of everything else, and it is the one layer Scopus has not given you a switch for.
Always test with difficult queries to see whether these features actually add value beyond conventional search.
Here we are ignoring systems that provide generative answers. Similar to its rival Clarivate, Elsevier offers RAG-based generated answers through paid modules such as Scopus AI and LeapSpace.
In the area of information retrieval, all embeddings are effectively vectors.
Other tools, such as Scopus AI and Web of Science Research Assistant, also use similar techniques, but in combination with other methods.
The phrase “LLM embeddings” also caught my attention. I may be reading too much into the wording, but it could suggest embeddings derived from newer generations of large language models, such as Qwen- or Gemini-derived embedding models, rather than the encoder-based models, such as BERT-based models, that have traditionally dominated dense retrieval. But “LLM embeddings” is loose terminology and, practically speaking, the distinction makes little difference for what I am discussing here.
Scopus exposing only the top 100 semantic results fits naturally with a nearest-neighbour retrieval model over a large vector index, although of course returning only the top-k results is not unique to vector search.
Combining vector search with filters is tricky. Filtered vector search is harder than ordinary vector search because the system must find the top-k most similar documents among only those that satisfy the filter. For example, if you want the 100 nearest documents published from 2020 onwards, retrieving the nearest 100 first and filtering afterwards may leave you with far fewer than 100 results. Pre-filtering, on the other hand, can reduce the efficiency of approximate nearest-neighbour indexes. Modern systems therefore use specialised approaches for filtered ANN search, such as ACORN.
That said, I did notice the following note in the Scopus documentation: “If enabled, the AI Summary option allows users to generate an AI summary based on the default top 20 results. This helps users understand the result set by providing an AI-generated overview of relevant content. Review the supporting documents and references before using the summary in your research.” I am unsure which particular product or feature this refers to.
It provides an Overview from the vector search that includes linked references, meant to include that above.
Separating interpretation, transformation and retrieval into layers is the clarification this conversation needed. Building the search for a scoping review is where it bites: a beautifully formed Boolean strategy built from a slightly misread question returns thousands of clean, precise, irrelevant records, and you do not find that out until you are deep into screening. Being able to inspect and edit the generated query before it runs is the part that actually matters.