This post is part of a “hot takes” series in which I make sharper claims than I usually do. I do not intend to offend, and I am not trying to tar every librarian with the same brush — the patterns I describe and perceive may be a function of my own local context.
I keep seeing advice aimed at researchers and librarians that goes something like this.
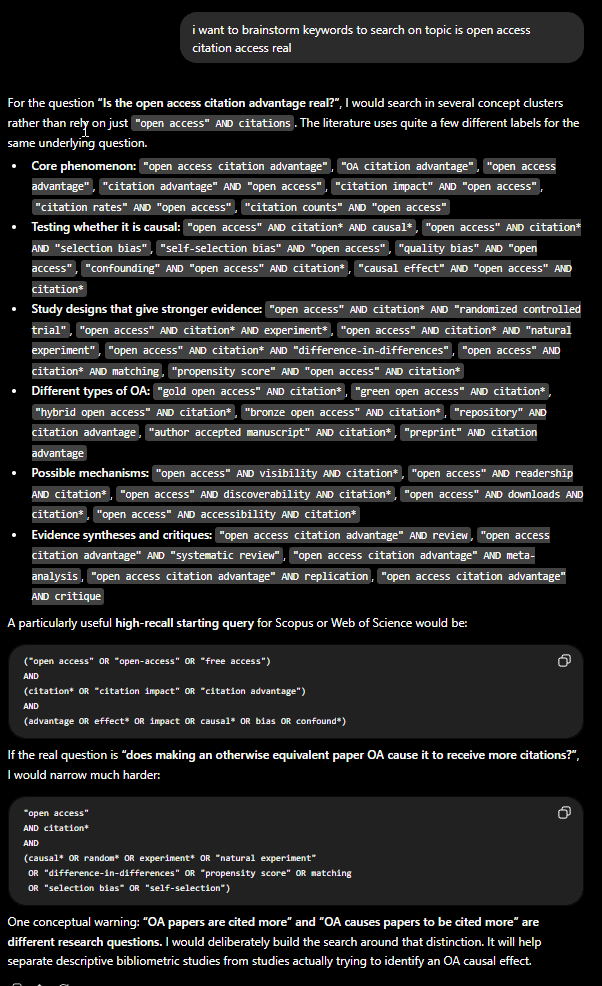
Do not use AI or LLMs to search. Instead, ask the LLM to brainstorm search terms, or even generate a full search strategy, which you then run yourself in a proper database. The idea is the human stays in control as the AI never touches retrieval, and nobody gets burnt by hallucinated references.
How about asking LLMs to brainstorm about topics and or gain some understanding of the field? That's a far more tricky subject that I am not touching here….
Below shows an example of such a use.
I am going to be controversial and say while this isn’t a horrible idea, this is often not the best idea, except in one specific case: you are doing formal evidence synthesis and the deliverable is literally a Boolean string. For everyone else, I think the advice should be inverted. Use AI powered search tools to actually search. Save the keyword brainstorming for later when your method genuinely demands it.
Thanks for reading Aaron Tay's Musings about Librarianship! Subscribe for free to receive new posts and support my work.
What do I mean by using AI to search?
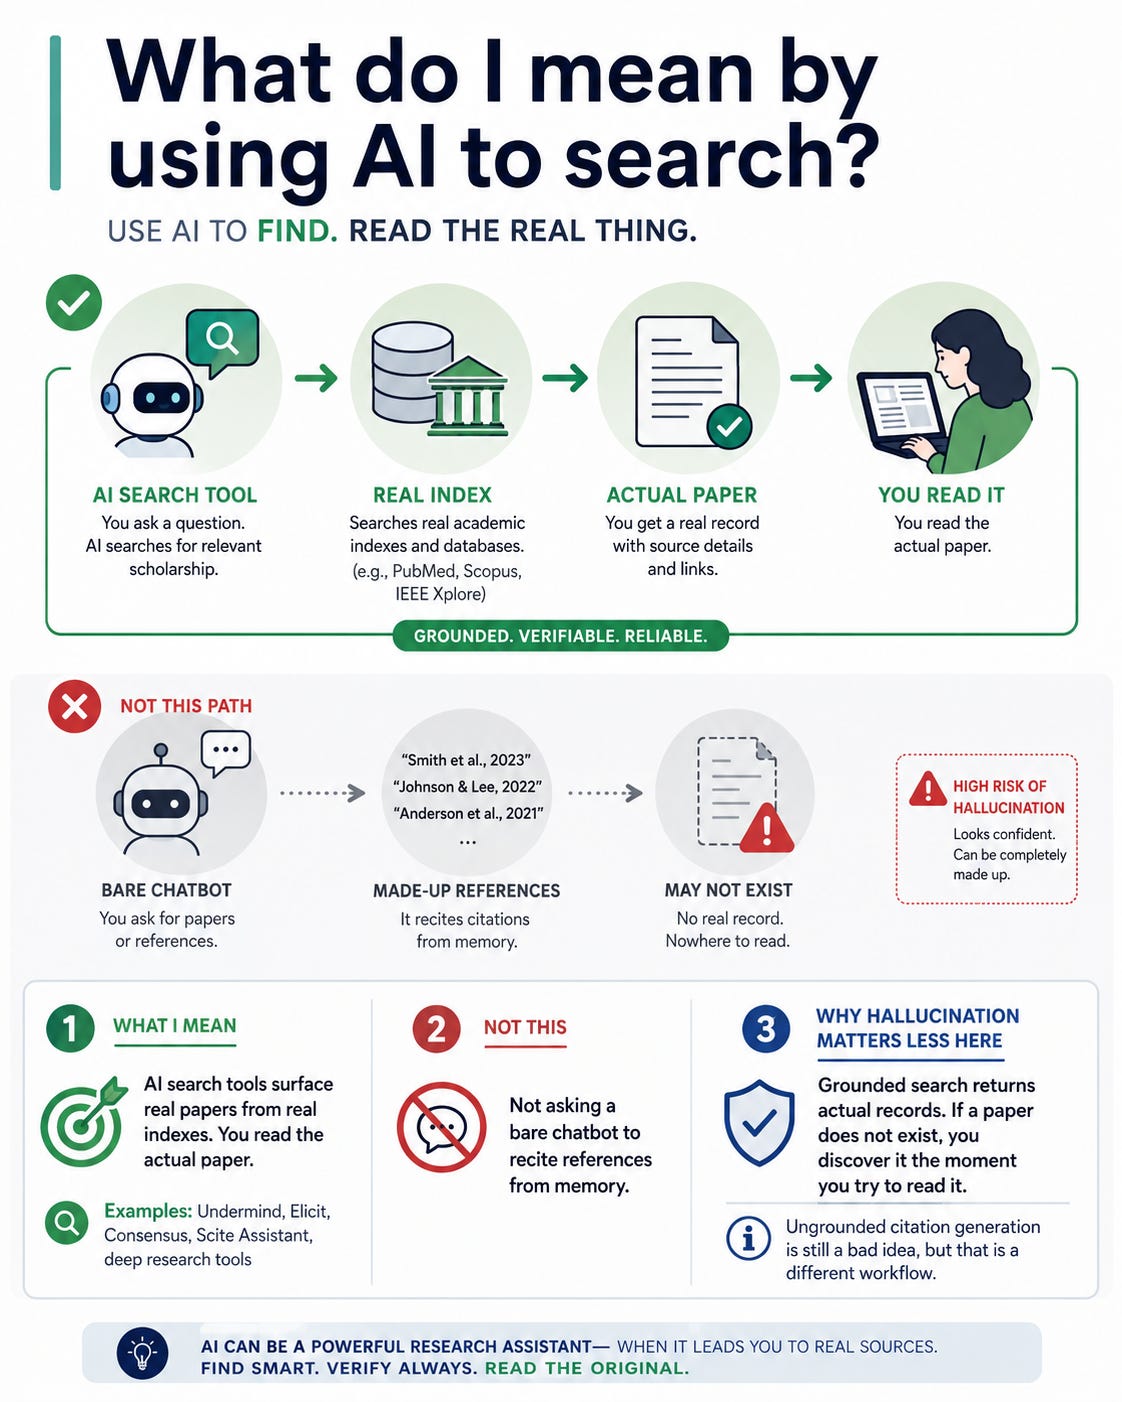
First, let me be clear about what I mean. When I say use an LLM to search, I literally mean the tool surfaces the paper and you actually read the paper. Think Undermind, Elicit, Consensus, Scite Assistant or the deep research modes of the frontier chatbots. The tool queries a real index, returns actual records, and you read them and/or mine them for keywords. I do not mean asking a bare chatbot to recite references from memory.
I know people worry about hallucination. If your mental model of AI search was formed only in 2023, when ChatGPT would happily generate ghost references, the brainstorm-only advice looks prudent.
But even if hallucinated references were still a serious problem in 2026 (they are not, at least for properly grounded search tools), it would hardly matter in this workflow. You are reading the actual paper. If the paper does not exist, you find out the moment you try to read it. Ungrounded citation generation from a bare chatbot is still a bad idea, but that is a different workflow, and not one anyone serious is recommending.
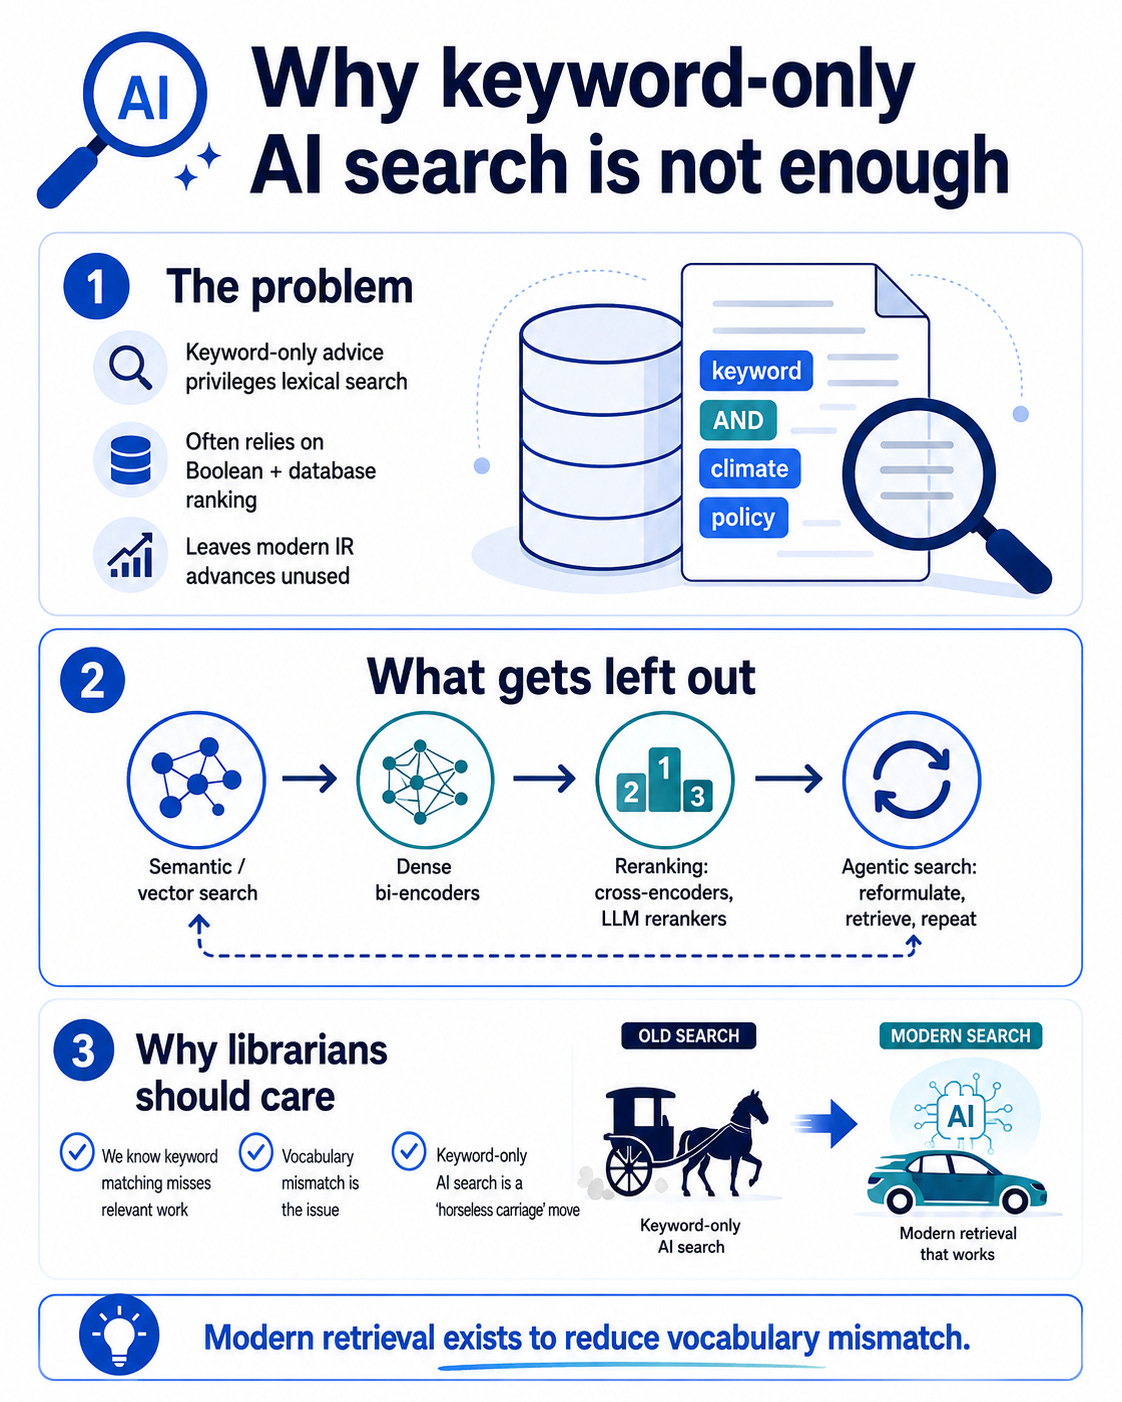
This advice throws away everything IR has learnt since 2018
Second, and this is my bigger objection, the advice privileges lexical search (and probably Boolean). If your keywords are simply passed into a conventional database search, you are usually relying primarily on lexical matching and whatever ranking pipeline1 that database provides. That leaves on the table a ton of information retrieval progress from the past decade or so.
Why using keywords all the time is not a good idea
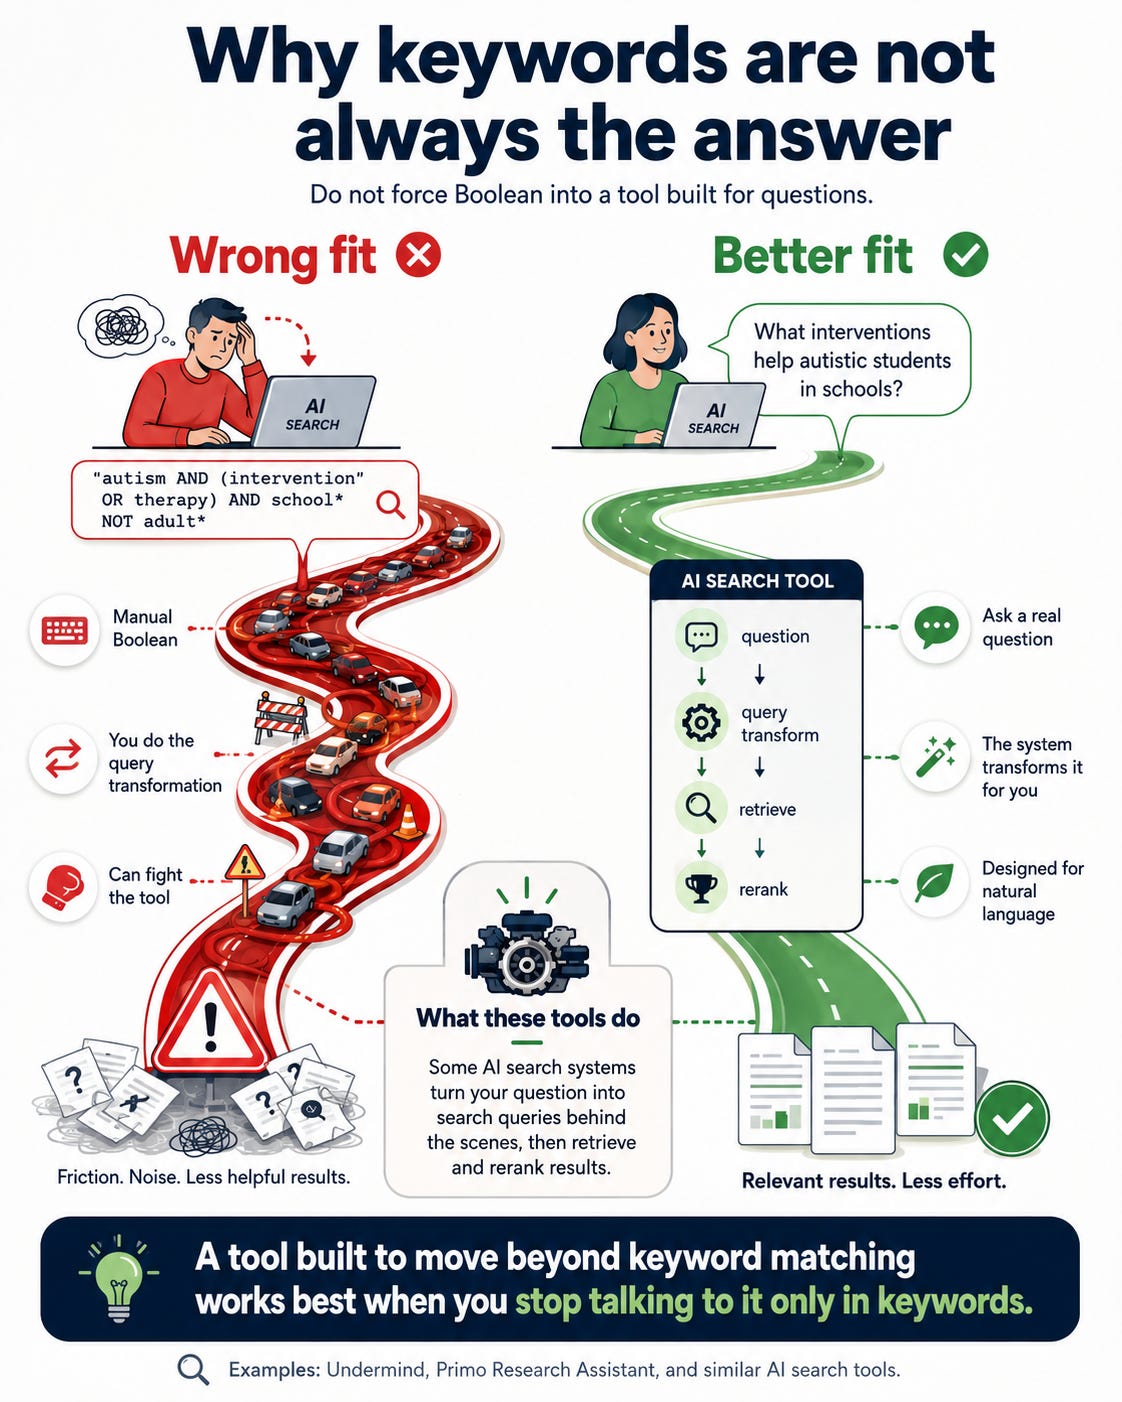
In fact, I can already picture one common failure mode. Someone asks ChatGPT for a Boolean string and then throws it into Undermind, Primo Research Assistant or another AI search tool designed to accept a natural-language research question. That is backwards. These systems may even still use lexical retrieval under the hood. For example Primo Research Assistant, for example, uses an LLM to transform the question into an OR-connected Boolean query for CDI retrieval, then reranks up to 30 results using embeddings but the point is that the system performs that query transformation for you. Feeding it a carefully constructed Boolean string means doing manually, and probably less effectively, something the retrieval pipeline was designed to handle itself.
If the AI search tool is mostly using dense embedding, natural language search queries will work better3, because nested parentheses and operators look nothing like the text the model was trained on. In either case, you have taken a tool designed to escape keyword matching and fed it keywords anyway.
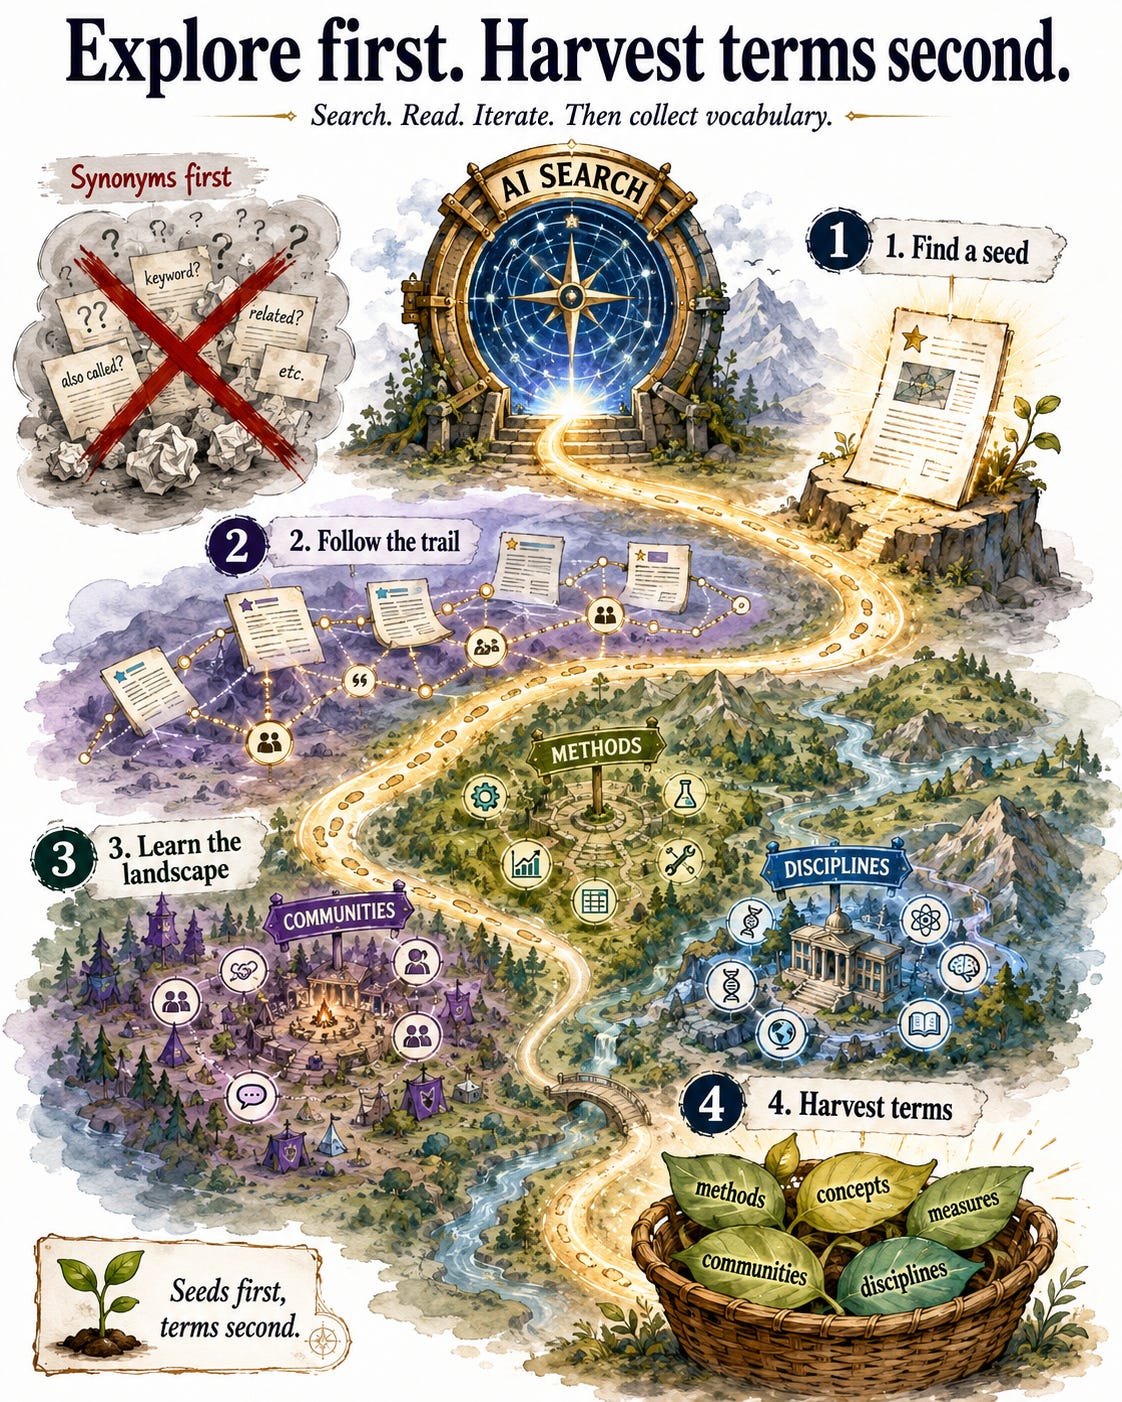
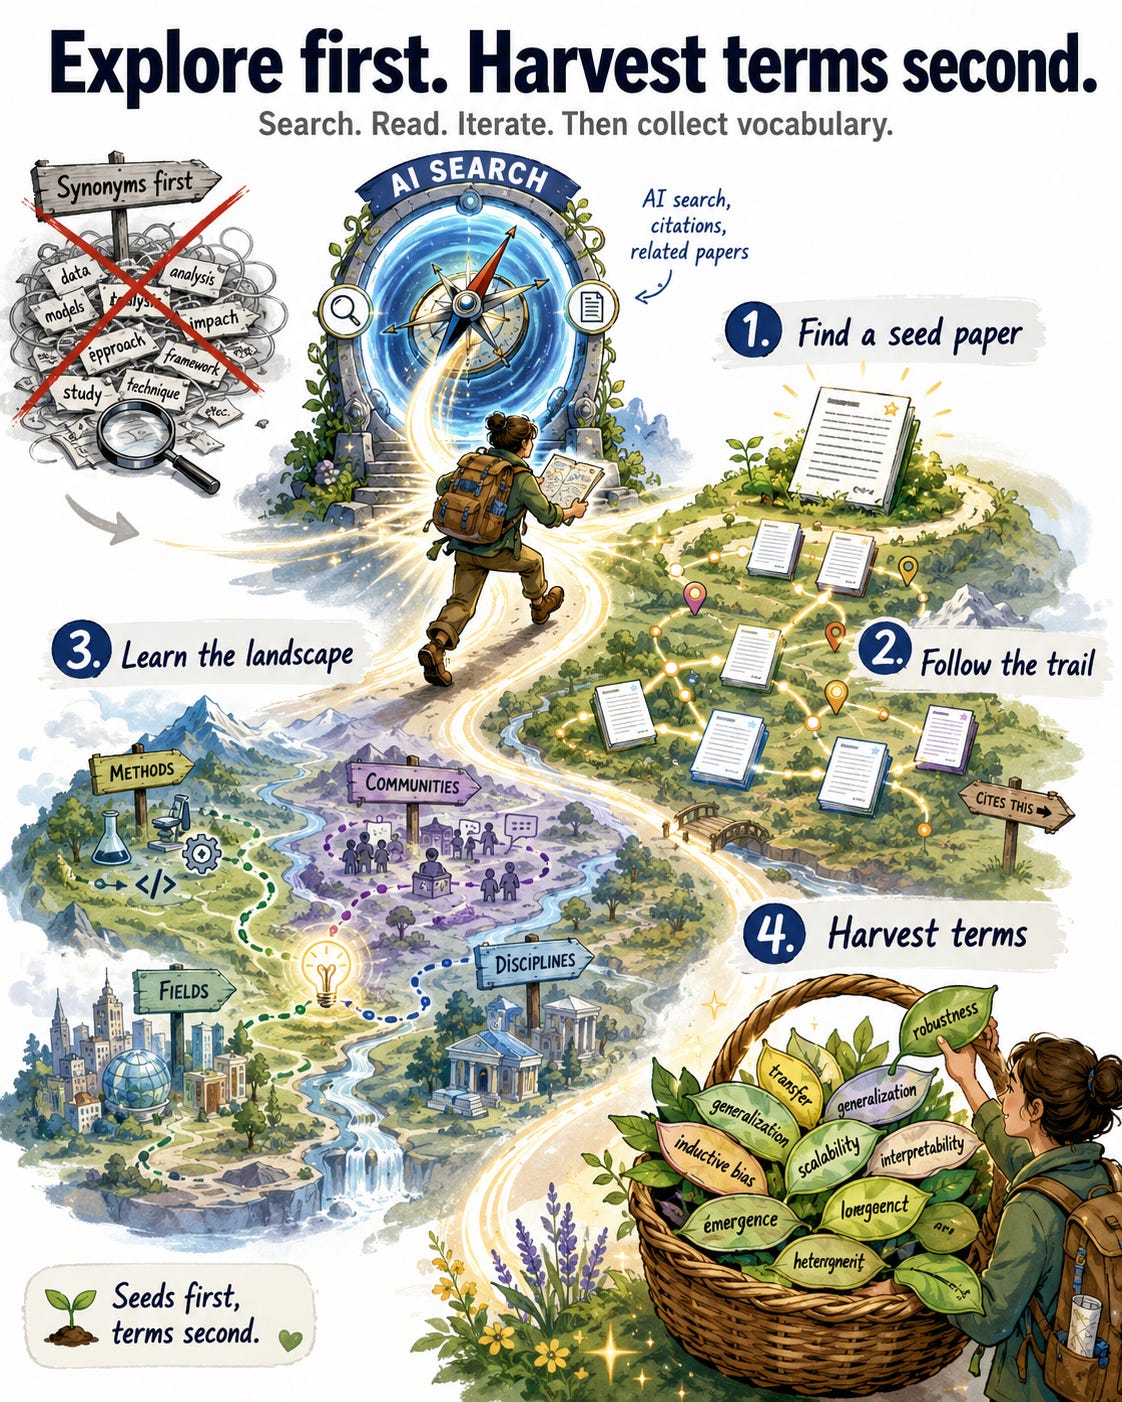
Invert the advice: explore first, harvest terms second
Instead I think the best way to use modern AI search tools is the opposite of what was advised at the start of this piece.
The best first move in a new literature is not to brainstorm vocabulary. It is to search, read and iterate with these tools!
A deep research tool like Undermind orients you on what is actually out there, the subcommunities, the recurring methods, the disciplinary homes of the problem, far better than staring at a list of synonyms an LLM guessed for you. Not everyone has access to the paid tools, but the argument does not hang on any one product. Even free options, say Asta Find Paper or the free tiers of the assistants named above, will orient you faster than a synonym list.
None of this is actually a new idea. Expert searchers have always known that the fastest way into a literature is one good paper. Citation pearl growing and Bates’ berrypicking model (Bates, 1989) both describe search as an iterative process that starts from found documents, not from a vocabulary you committed to in advance. Even the evidence synthesis world, when it develops search terms rigorously, does so empirically. Tools like litsearchr mine candidate terms from the text of known relevant records (Grames et al., 2019) rather than asking anyone, human or machine, to introspect a term list. Seeds first, terms second. AI search is simply the most powerful seed finding instrument we have ever had.
The strongest objection I expect is transparency. These tools rarely disclose their full coverage, and their ranking is opaque. So the worry is that exploring with them bakes unknown bias into your seed set.
First, exploration has never been 100% transparent even in the “good old days”. Footnote chasing, shelf browsing, asking a colleague who knows the area. None of these classic orientation moves came with a documented coverage statement either. We have always reserved rigour for the final reported strategy, not the exploratory stage, and rightly so. Second, seeds get corrected downstream. You read the papers and chase their citations in both directions, which pulls in what the seeds missed. If you go on to build a formal strategy, term harvesting widens the net well beyond your starting set. An iterative process is robust to an imperfect first step. That is the whole point of berrypicking.
To be clear, coverage transparency is a fair demand to make of vendors, and I intend to keep making it. But it is an argument for better disclosure, not for guessing words instead of searching.
The low bandwidth problem
Here’s an honest question. Why do we want to brainstorm keywords with an LLM in the first place? We are hoping to exploit what it learnt during pretraining: associations between concepts, terminology, disciplines and related ideas. But making it express all of that as a list of keywords is an extremely low bandwidth channel. We are asking a system that represents concepts in rich, high-dimensional form to compress those relationships into a dozen strings, which we then pipe into a query language designed decades ago for humans sitting at terminals.
I am not arguing that brainstorming is useless. Rather, it is better to find papers that are definitely relevant, then brainstorm!
When an AI search system can instead use that information to transform queries, retrieve from a live index, rerank what comes back and reformulate when necessary, far more of that capability can be brought to bear on the search problem. Crucially, the process is also grounded against an actual corpus, rather than relying only on an LLM to brainstorm terminology from its pretraining.
Our big is the difference between asking the LLM to just rely only on their pretraining knowledge? Very big.
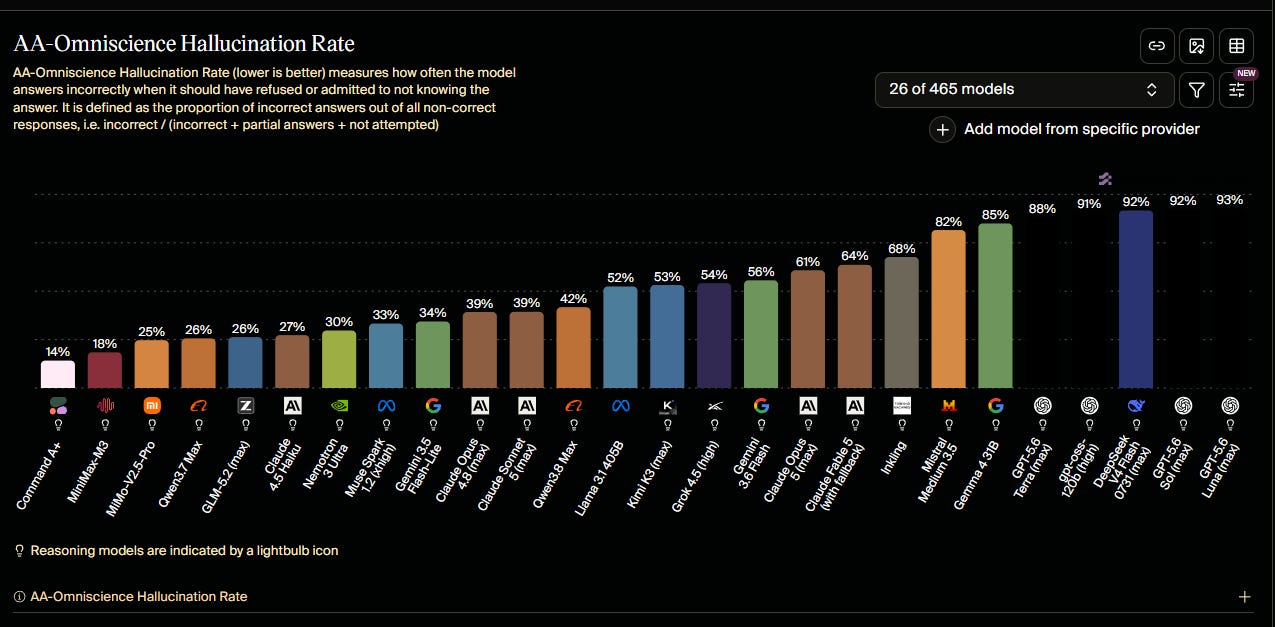
Artificial Analysis’s AA-Omniscience benchmark shows that even frontier models still hallucinate frequently on difficult factual questions when forced to rely only on pretraining without search. Even leading models still show substantial hallucination rates on this deliberately difficult benchmark: current frontier examples are at best in roughly the 35–50% range, though rates vary considerably by model. Anti-AI people reading this should not jump to rejoice. Two important things to note. Firstly, as already mentioned this is a closed-book test: models receive no supporting context and have no access to web search, retrieval or other tools. The benchmark is therefore testing the model’s internal factual knowledge and, crucially, whether it knows when to abstain rather than guess. Its “hallucination rate” is not simply the percentage of all answers that are wrong; it measures how often the model gives an incorrect answer when it fails to know the correct one
Asking the LLM to brainstorm keeps the ungrounded part (its reconstruction from pretraining) and throws away the retrieval process that can test those ideas against real records.
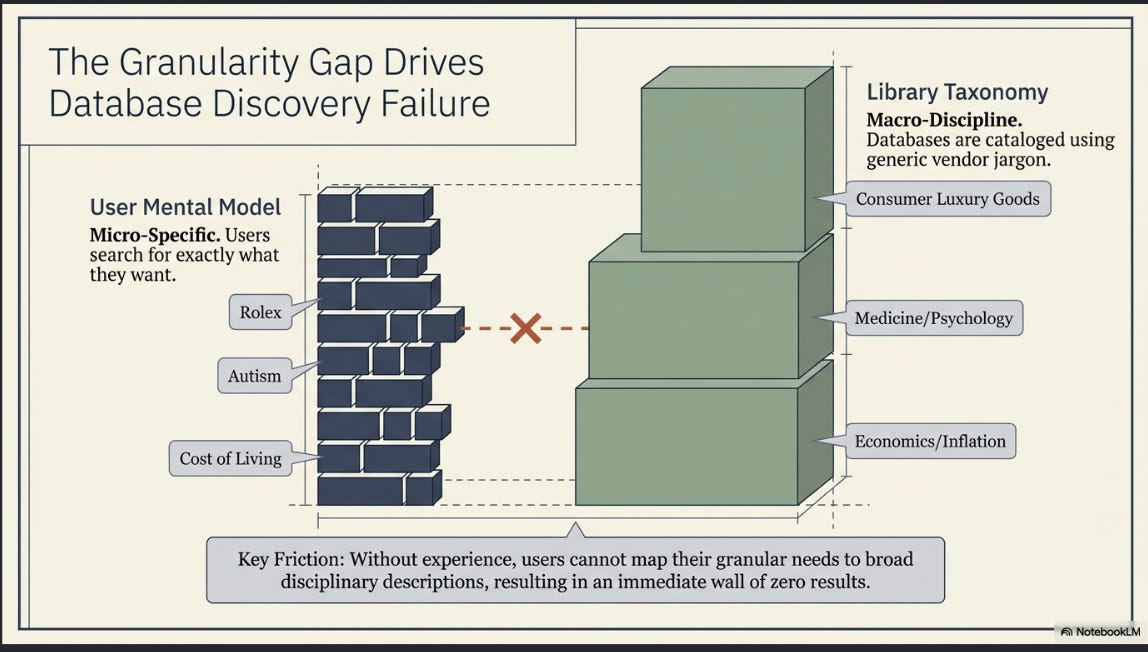
Pretraining gives the model a rough map of how topics relate to disciplines, concepts and resources. So when a search for “autism” finds no suitable database to use, it can move up a level and try psychology, medicine or special education; when “Rolex watches” fails, it can recognise that what you probably need is a consumer, luxury-goods or market-research database; and when “cost of living” gets nowhere, it can try inflation, household expenditure or consumer prices instead.
When searching for suitable databases, agentic search is able to learn from the earlier failure adjust and change to the right keyword.
Grounding then tests those guesses against what is actually available in the library’s index. And the agentic loop is what lets the system recover when the first idea fails: search, look at what came back, broaden or shift the concept, and search again. It can even change strategy altogether — for example, suggesting Orbis or Capital IQ when the library does not subscribe to Hoover’s.
That is the part brainstorm-only advice misses. It keeps the model’s prior knowledge “what words or concepts might be related to this?” but throws away both the grounding against real records and the ability to learn from a failed search and try something different.
Thanks for reading Aaron Tay's Musings about Librarianship! This post is public so feel free to share it.
In short, don’t force a modern search system into a workflow where the LLM’s only contribution is guessing keywords before retrieval. Give the system the information need, let it retrieve and iterate against an actual corpus, inspect what it finds, and harvest vocabulary from evidence rather than from the model’s ungrounded parametric memory. Then you can use that to brainstorm keywords if that is what you need or want.
For high-recall evidence synthesis, established systematic database searching remains the primary retrieval method. Current Cochrane/RAISE guidance as of March 2026 treats agentic search tools such as Elicit, Undermind and Asta Find Paper (which are named) as useful “acceptable for use” for exploring the literature, but not as replacements for formal evidence retrieval.
I stand beside you. Dead on. I've given up reading online advice expecting to learn something useful and instead use it as a tool to observe what others are actually doing. I'm always pleasantly surprised when I'm in agreement or learn something new!
This advice is generic as well as the recommendation to brainstorm on synonyms or ask LLM to create Boolean query. When I teach I make sure that students learn disciplinary vocabulary first, understand concepts and constructs. Librarians who are not familiar with disciplinary terminology might consider “talking” with generic LLM and be impressed with all terms it expounds from large datasets.


I stand beside you. Dead on. I've given up reading online advice expecting to learn something useful and instead use it as a tool to observe what others are actually doing. I'm always pleasantly surprised when I'm in agreement or learn something new!
This advice is generic as well as the recommendation to brainstorm on synonyms or ask LLM to create Boolean query. When I teach I make sure that students learn disciplinary vocabulary first, understand concepts and constructs. Librarians who are not familiar with disciplinary terminology might consider “talking” with generic LLM and be impressed with all terms it expounds from large datasets.